Connected workflows
Move data cleanly between forms, inboxes, CRMs, accounting tools and internal systems.
Automation that clears the busywork
We take the repetitive, error-prone work and make it run by itself. AI where it helps, simple automation everywhere else.
Start a conversation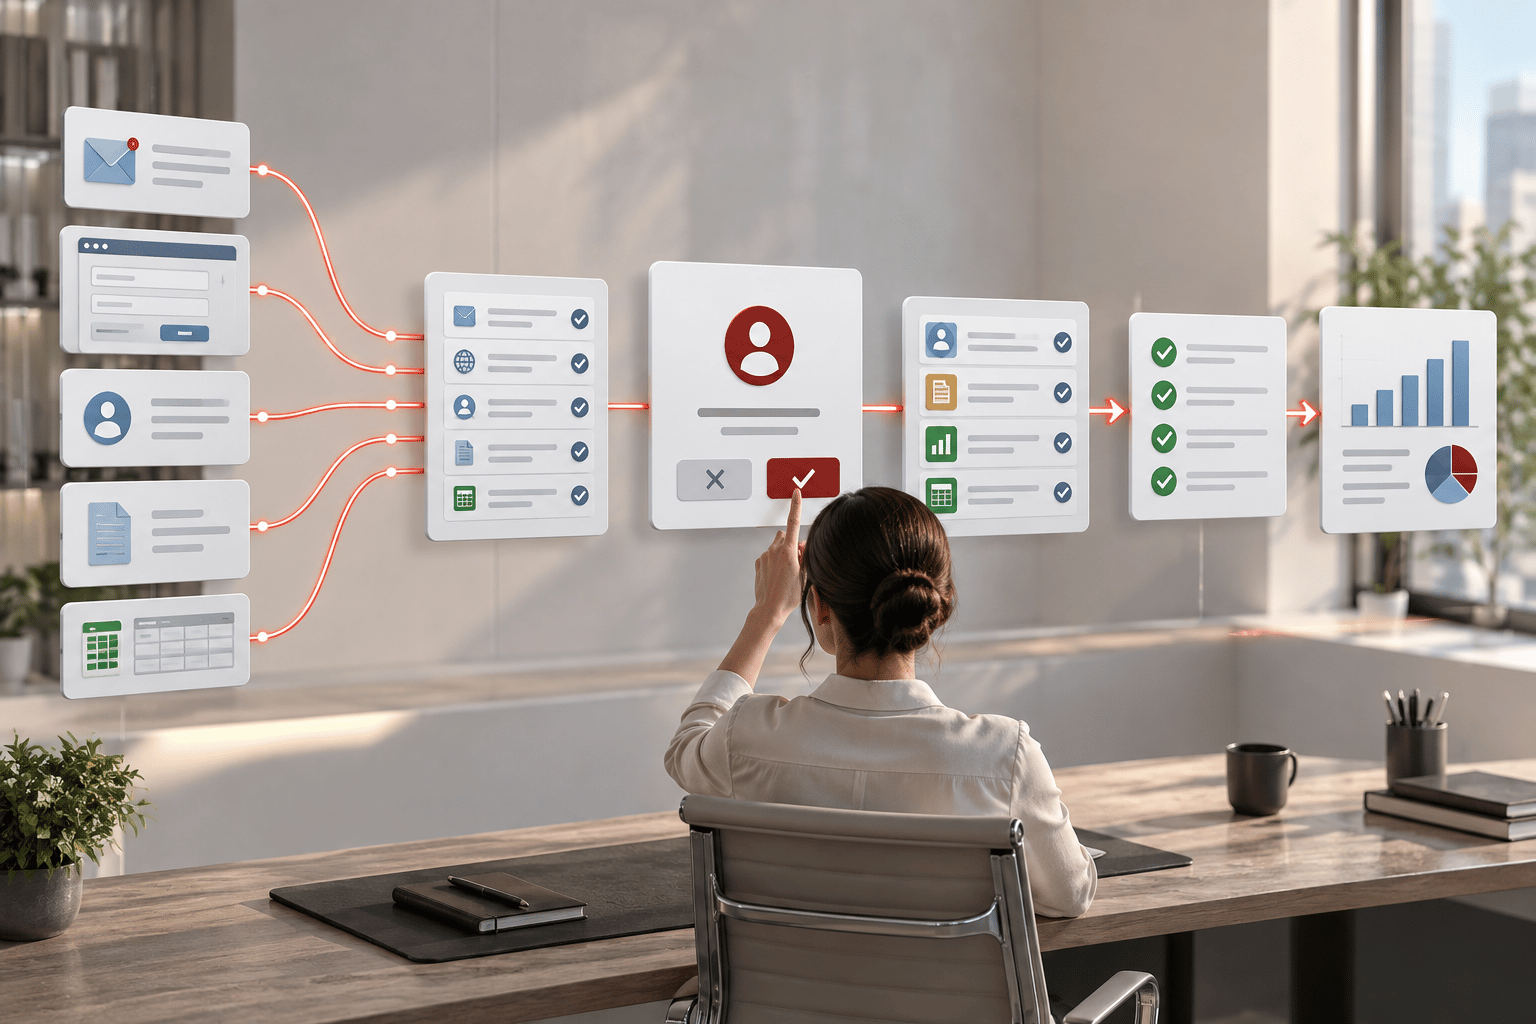
Tools we automate with
Useful outcomes
Move data cleanly between forms, inboxes, CRMs, accounting tools and internal systems.
Classify, extract, summarise or draft, with human review wherever consequences require it.
Make the state of a process visible instead of hiding it across messages and spreadsheets.
The admin work runs itself. People do the work that needs a brain.
Quick estimate
Rough numbers are fine. This runs entirely in your browser, and nothing is sent anywhere.
Based on 45 working weeks per year. This is the cost of the work, not guaranteed savings. Automating half would save roughly half.
What is included
How we work
01
Document the actual process, including exceptions people stopped mentioning years ago.
02
Choose what to automate, what to leave human and how failures should be handled.
03
Test a narrow, valuable path with real inputs before expanding the system.
04
Deploy with logs, alerts, ownership and a practical route for ongoing improvement.
Data flow, retention, provider terms and access are reviewed before implementation. Sensitive steps can use restricted providers, self-hosted components, redaction or no AI at all.
Start with the most boring, repetitive tasks, especially the ones that consume the most time. Removing trivial work first gives the team time back quickly and proves the workflow before anything more ambitious is automated.
Usually. We first look for supported APIs, webhooks and exports in the tools you already use. If the only connection is fragile or unofficial, that limitation is made explicit before it becomes operationally important.
A focused workflow can often be mapped and proven in weeks. Timing grows with the number of systems, undocumented exceptions, security requirements and the consequences of a failed step.
Important workflows launch with logs, alerts, retries and a clear route for human review. The team can see the current state, correct an exception and pause the flow instead of discovering silent errors weeks later.
Our approach
Sometimes the answer is a language model, sometimes plain rules or an API. We pick what is reliable and private, and never force AI in for its own sake.
In detail
Every project starts by following a single request from the moment it arrives to the moment it is finished. Who touches it, which tools it passes through, where the same information gets typed a second time, and which cases people quietly handle by hand. What looks like one process is usually three, held together by exceptions nobody ever wrote down because everybody already knows them.
That map tends to change the brief. Often the expensive part is not the work but the waiting between steps, with a request sitting in an inbox for two days because nobody knew it had arrived. Sometimes one validated field at the source removes more rework than a large automation would. We would rather tell you that in the first week than build what was asked for and watch it run a broken process faster.
You already have a CRM, a mailbox, an accounting package and a handful of forms. The work is getting them to agree with each other. Where there is a clean API, we use it. Where there is not, there is usually a webhook, a scheduled export, or a structured email or PDF worth parsing. You will hear which of those routes is fragile before anything important comes to depend on it.
Every connection gets one source of truth and a decided answer for the bad days, because the bad days arrive. Messages get delivered twice. A service is unavailable for an hour. A file turns up missing a field it has always had. A workflow that has not decided what to do in those moments does not fail loudly; it fails quietly, and you find out weeks later from a customer. Retries, steps that are safe to run twice, and a queue for anything a person needs to look at belong in the build, not in a later phase.
Language models are good at one class of work: reading messy input and turning it into something structured. Sorting what arrives, pulling fields out of invoices that never look the same twice, summarising a long thread, drafting a first reply, answering from your own documents. A model gets one job, the least context it needs to do it, and an output shape the rest of the system can check before acting on it.
Everything else stays ordinary code. Permissions, totals, business rules, anything irreversible: those have to behave identically every time, and a model does not offer that. How much review a step needs follows what it costs to get wrong. A misfiled email is free. A payment or a promise to a customer waits for a person. Where it matters, prompts, model versions and outputs are logged, so a bad result can be explained rather than guessed at.
Models are also replaced every few months. Keeping them behind a narrow interface means swapping one is an afternoon of work instead of a rebuild.
Before anything runs, we write down what each step touches, where it travels and who can read it. Credentials are separated per environment and scoped to the permissions the workflow uses, which is rarely the set that was convenient to create. Sensitive material can be redacted before it leaves, sent only to a provider you have approved, or kept away from AI services altogether. A great deal of useful automation involves no model at all.
When data genuinely cannot leave, self-hosted components are a real option, and we will say so before anyone defaults to the nearest API. Retention follows what the business and the GDPR actually require, not what a tool happens to default to. This is the awkward part to retrofit, so it comes before the build.
Three failures show up again and again. The first is automating a process that should have been deleted. The second is a workflow with no owner, which rots the first time a supplier changes an export format. The third is an integration built on something undocumented, a scraped page or an unofficial endpoint, that works beautifully until the day it does not.
None of them are exotic and all of them are avoidable. Delete first, automate second. Name an owner before launch. Build on interfaces the vendor actually supports, and when a fragile route is the only route, treat it as a known risk with a monitor on it. A line in a handover document nobody reads is not a mitigation.
An automated process should be easier to see than the manual one it replaced. Its current state lives somewhere the team already looks. Exceptions arrive with enough context for the person responsible to resolve them without calling a developer. Anyone can pause a flow, correct a record and let it carry on.
We agree a baseline before launch (handling time, backlog, error rate, how many cases still need a human) so that afterwards there is something honest to compare against. Not every number moves, and the ones that do not are worth knowing about. What gets handed over with the workflow:
We will not make a broken process run faster, put an irreversible decision in a model’s hands or force AI into work that plain rules handle better. The system must remain visible, reviewable and stoppable.
Tell us what is slowing you down. You will get a straight answer.